
The training platform for specialised agents
Overmind turns your production traces into specialised models you own, automatically trained, benchmarked, and served.

A Complete AI Lab for Your Engineering Team
Overmind sits directly between your observability stack and your inference layer. It continuously metabolizes live agent behavior into custom, hyper-specialized models.
Codebase Integration & Context Graph
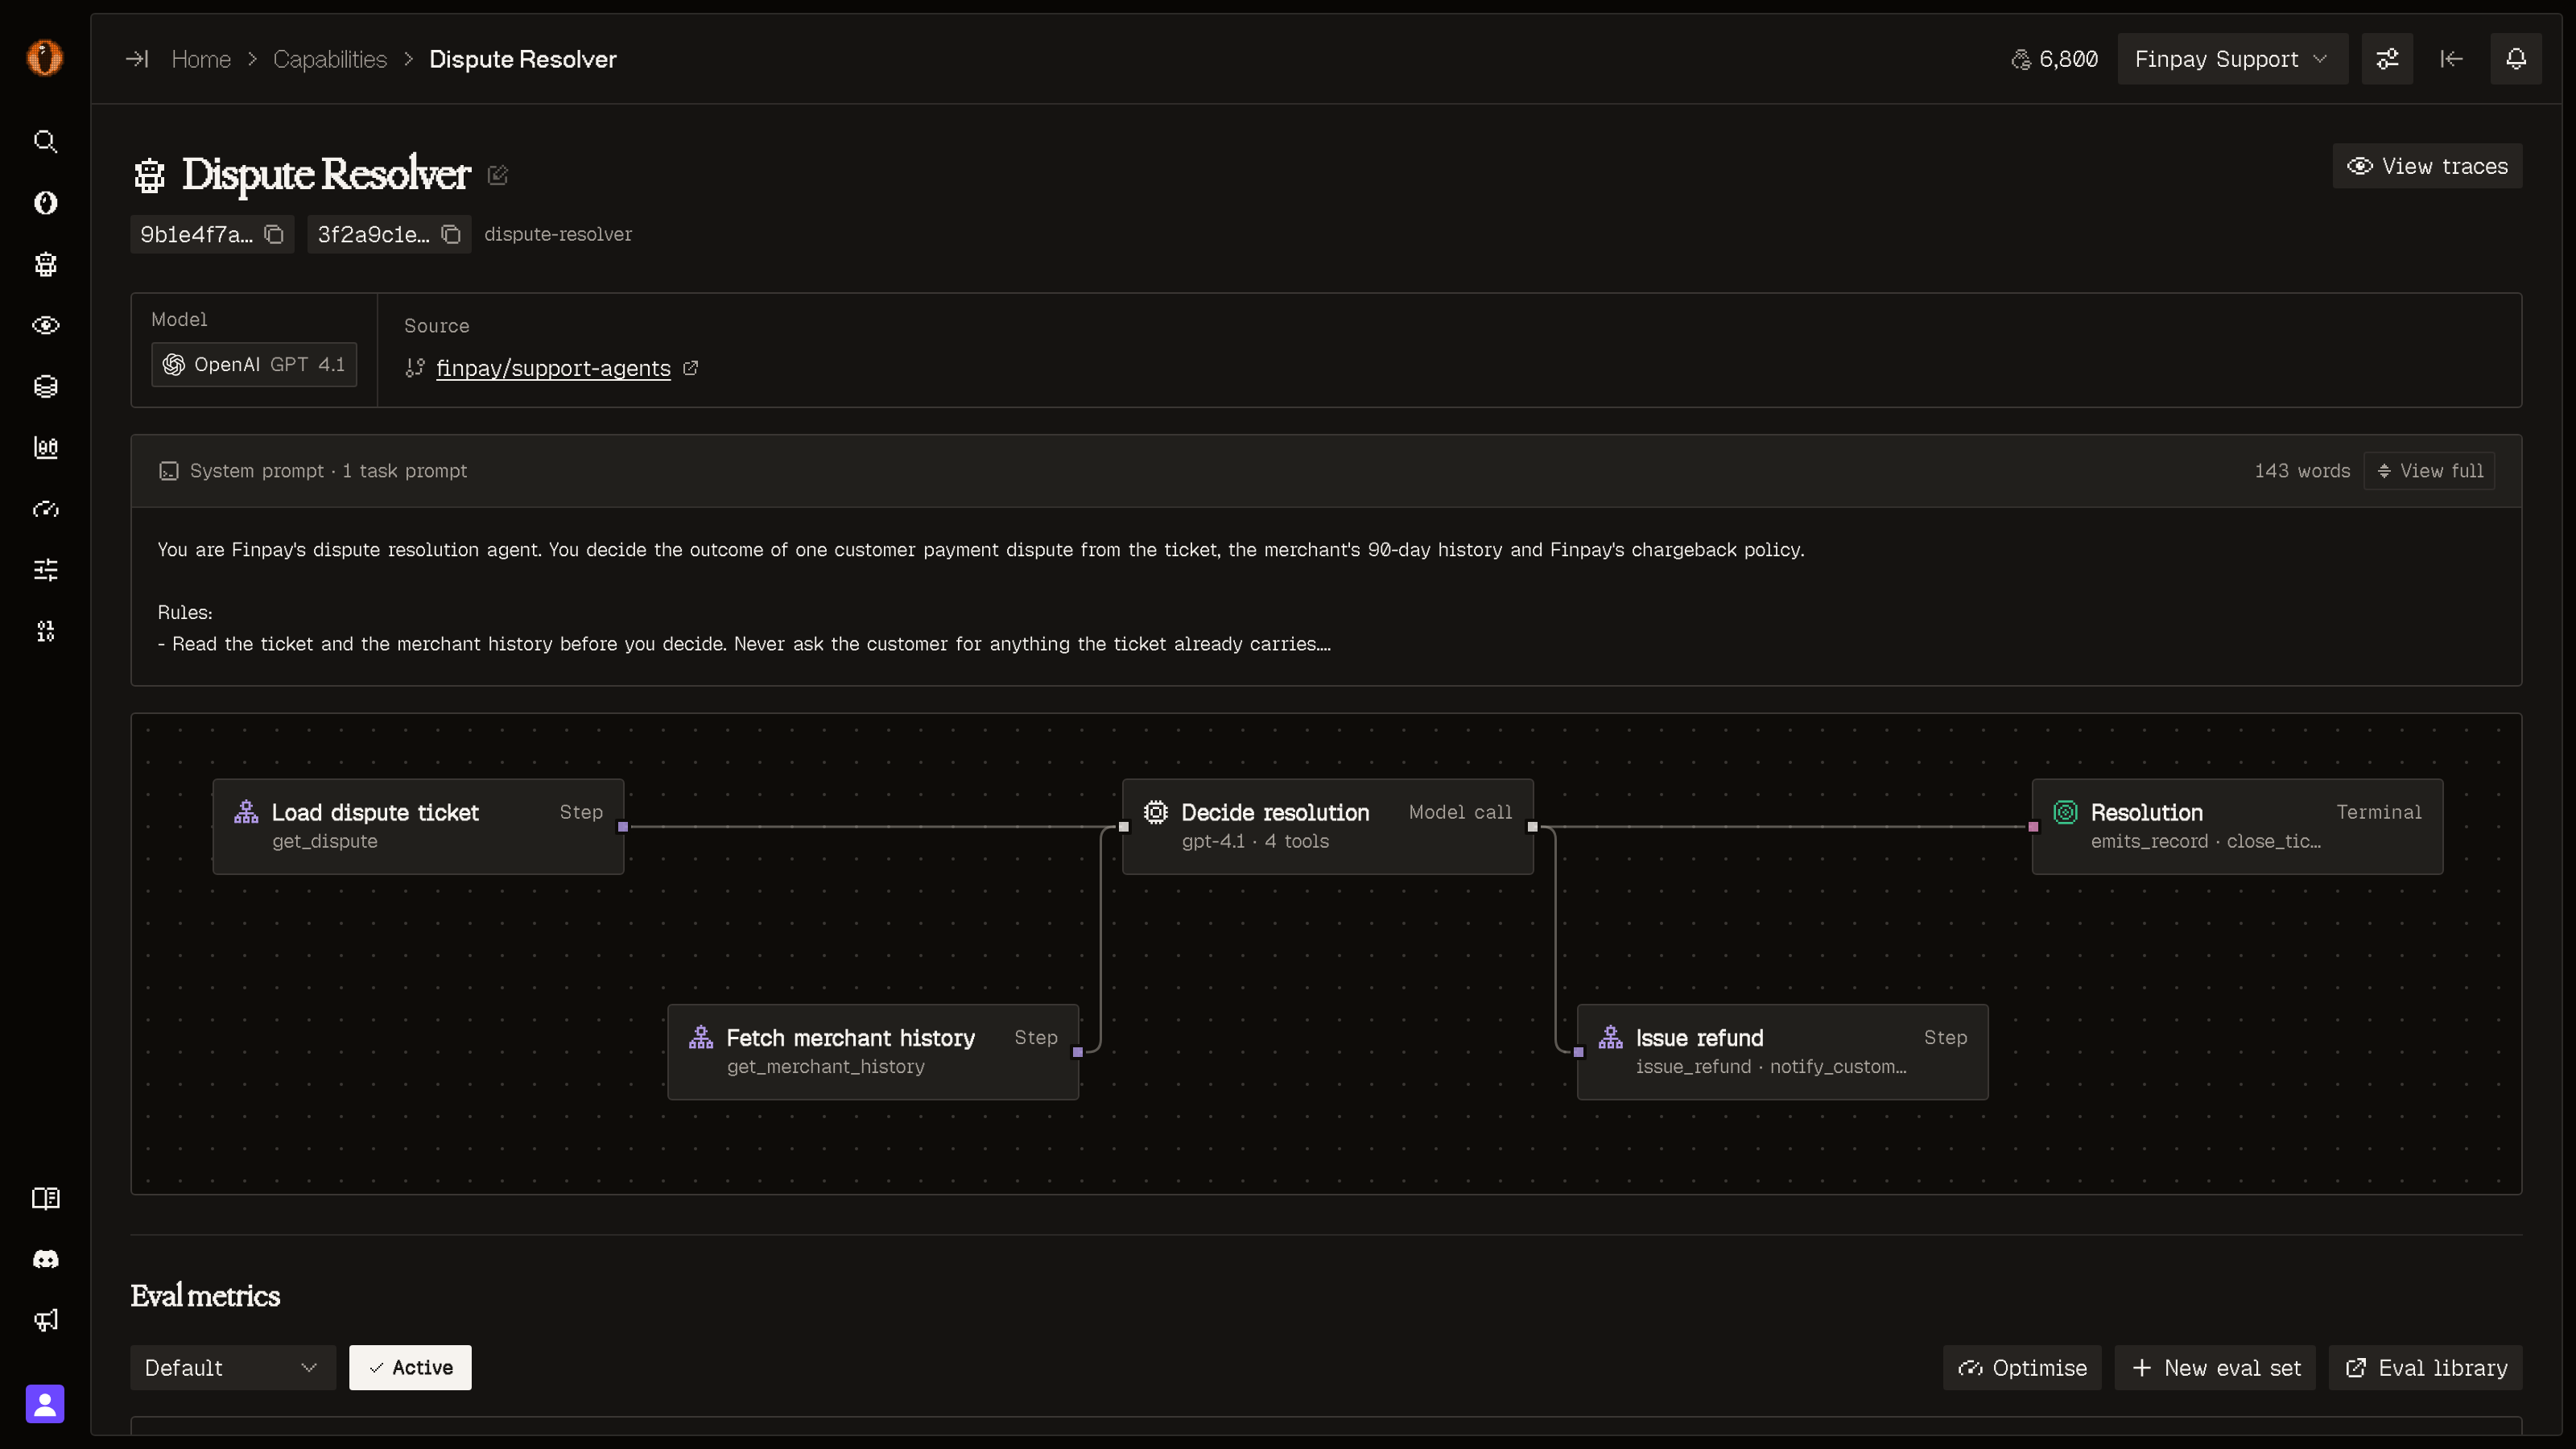
Connect Overmind to your repository. The harness scans your codebase, maps your tool signatures, and automatically constructs a context graph of your agent's capabilities.

The agent context graph
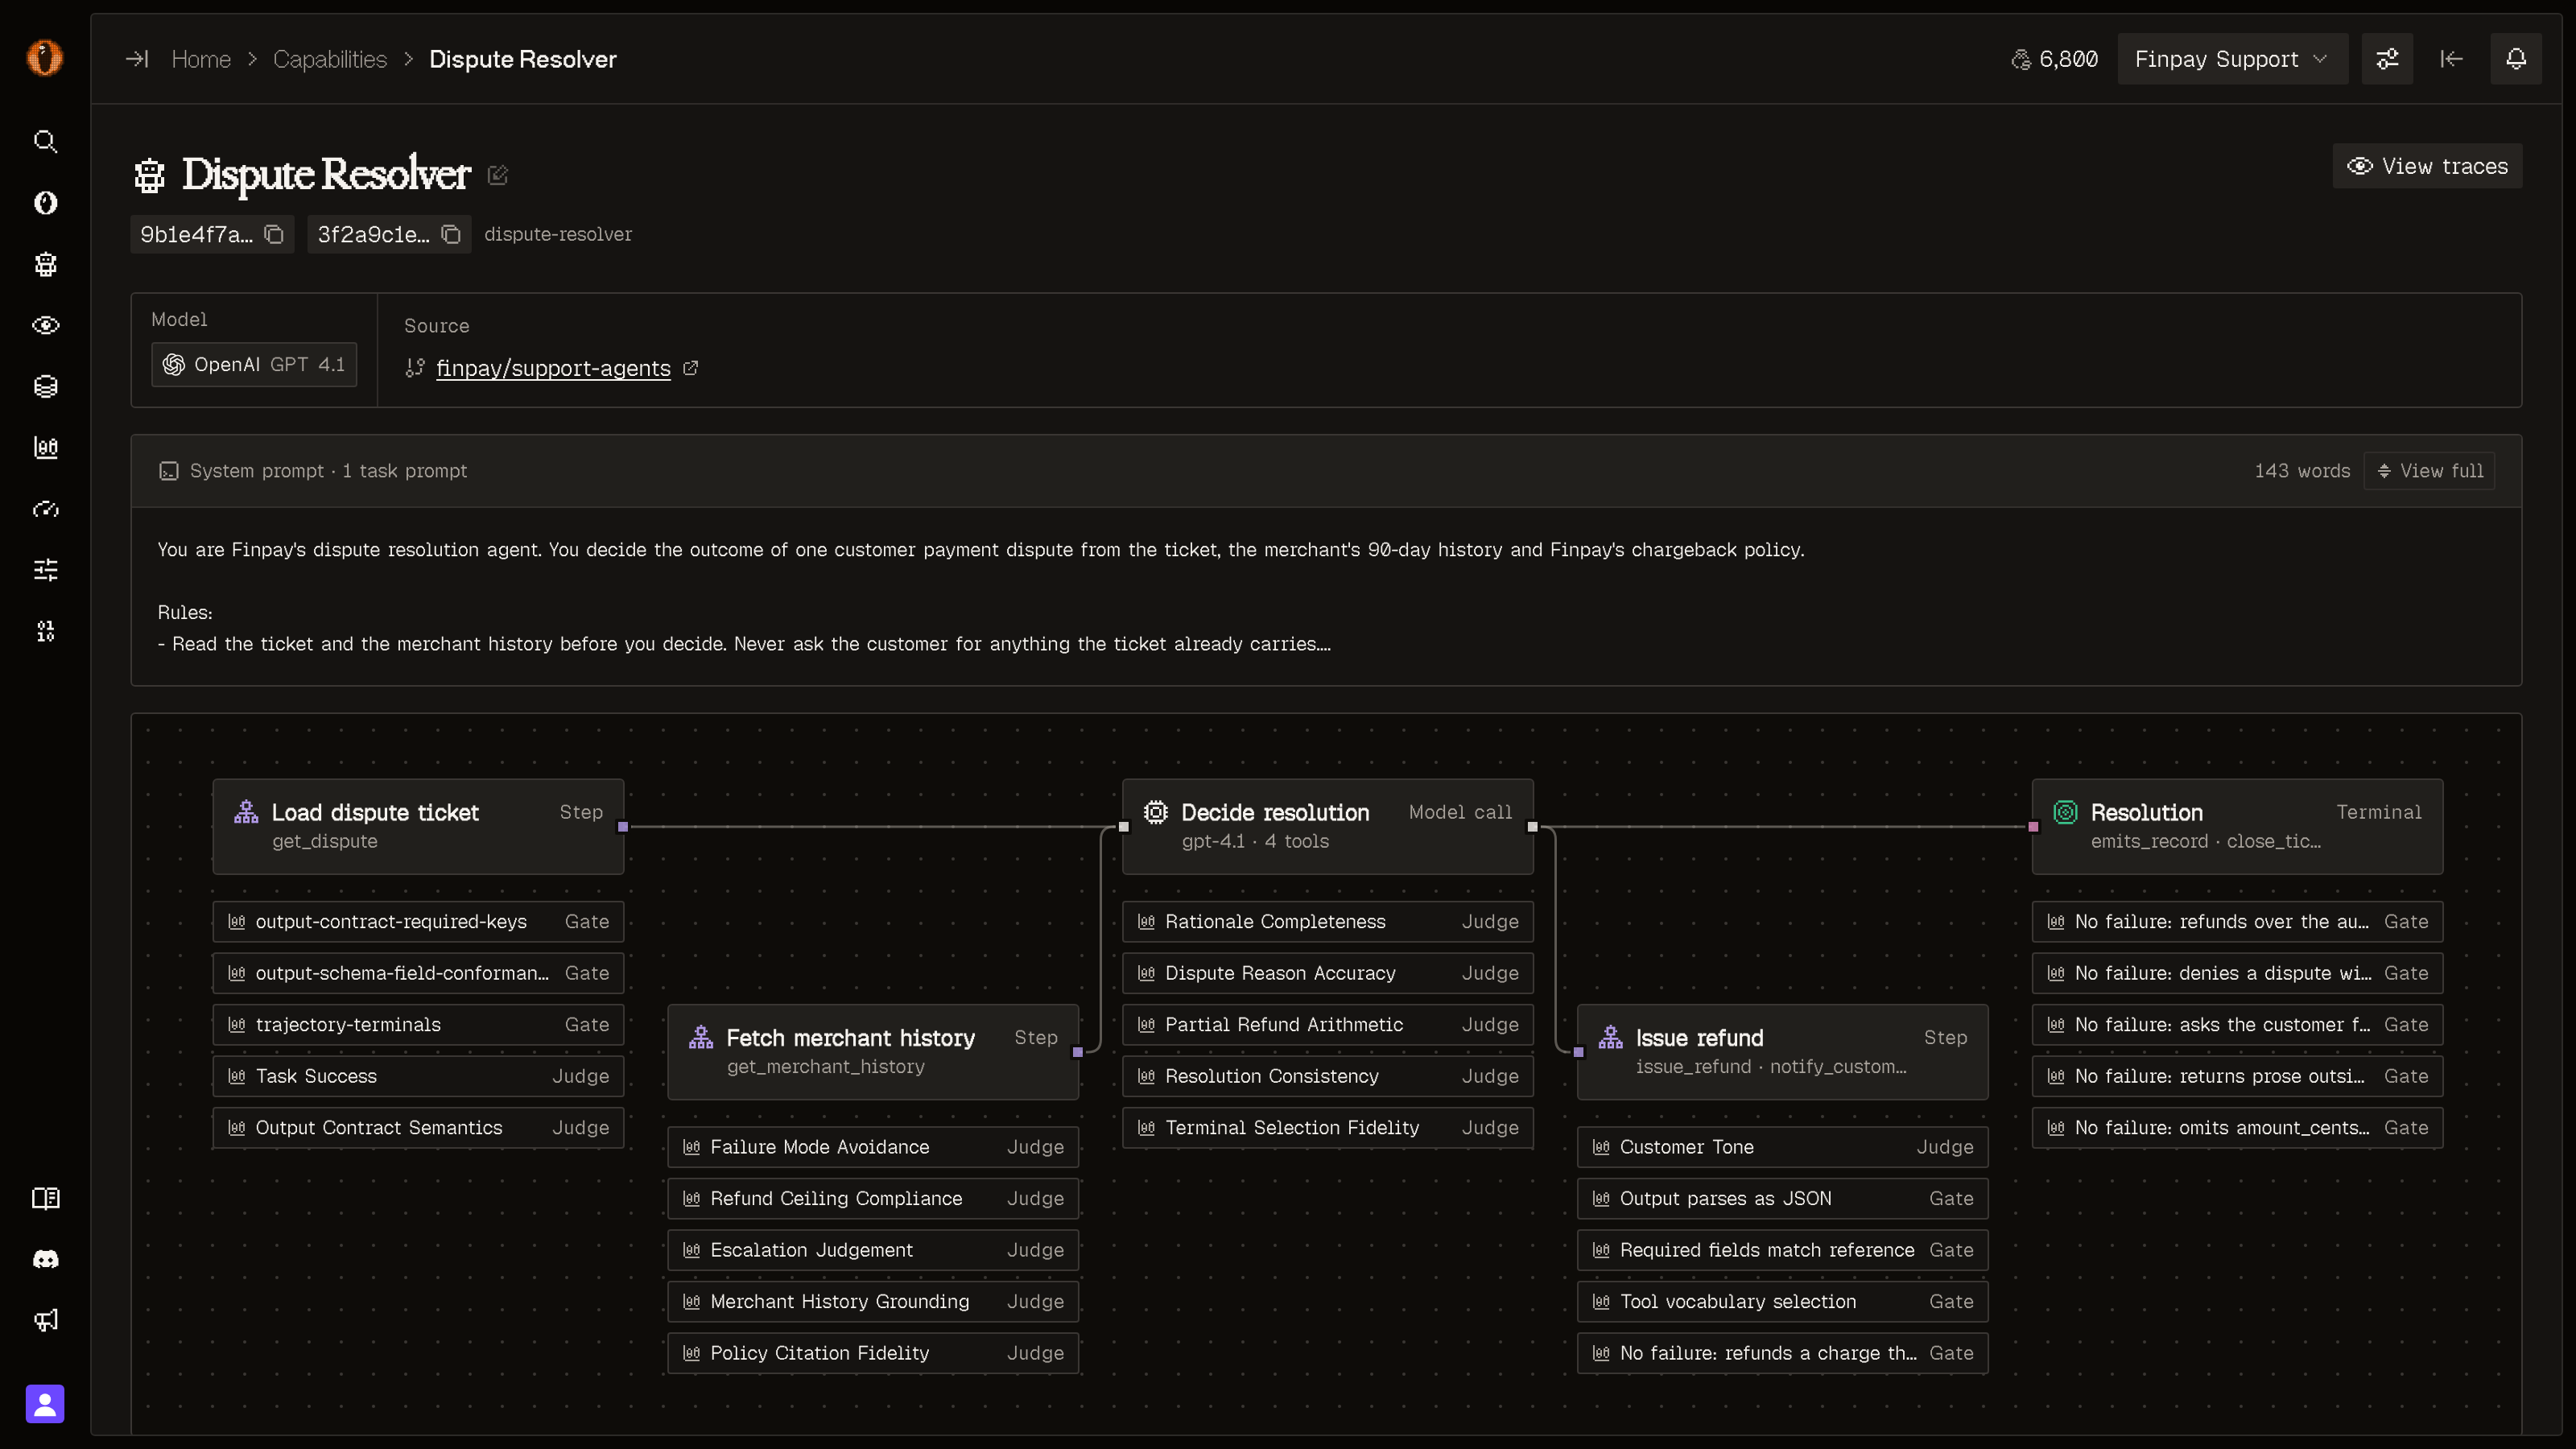
Your biggest edge is knowing your agent completely. Overmind maps your whole agent into one graph: every prompt, tool, decision path, and dependency, discovered from the codebase and kept honest by traces from a single SDK setup. Evals, datasets, optimisation, and training all draw from that one shared picture.
Automated Data Workshop
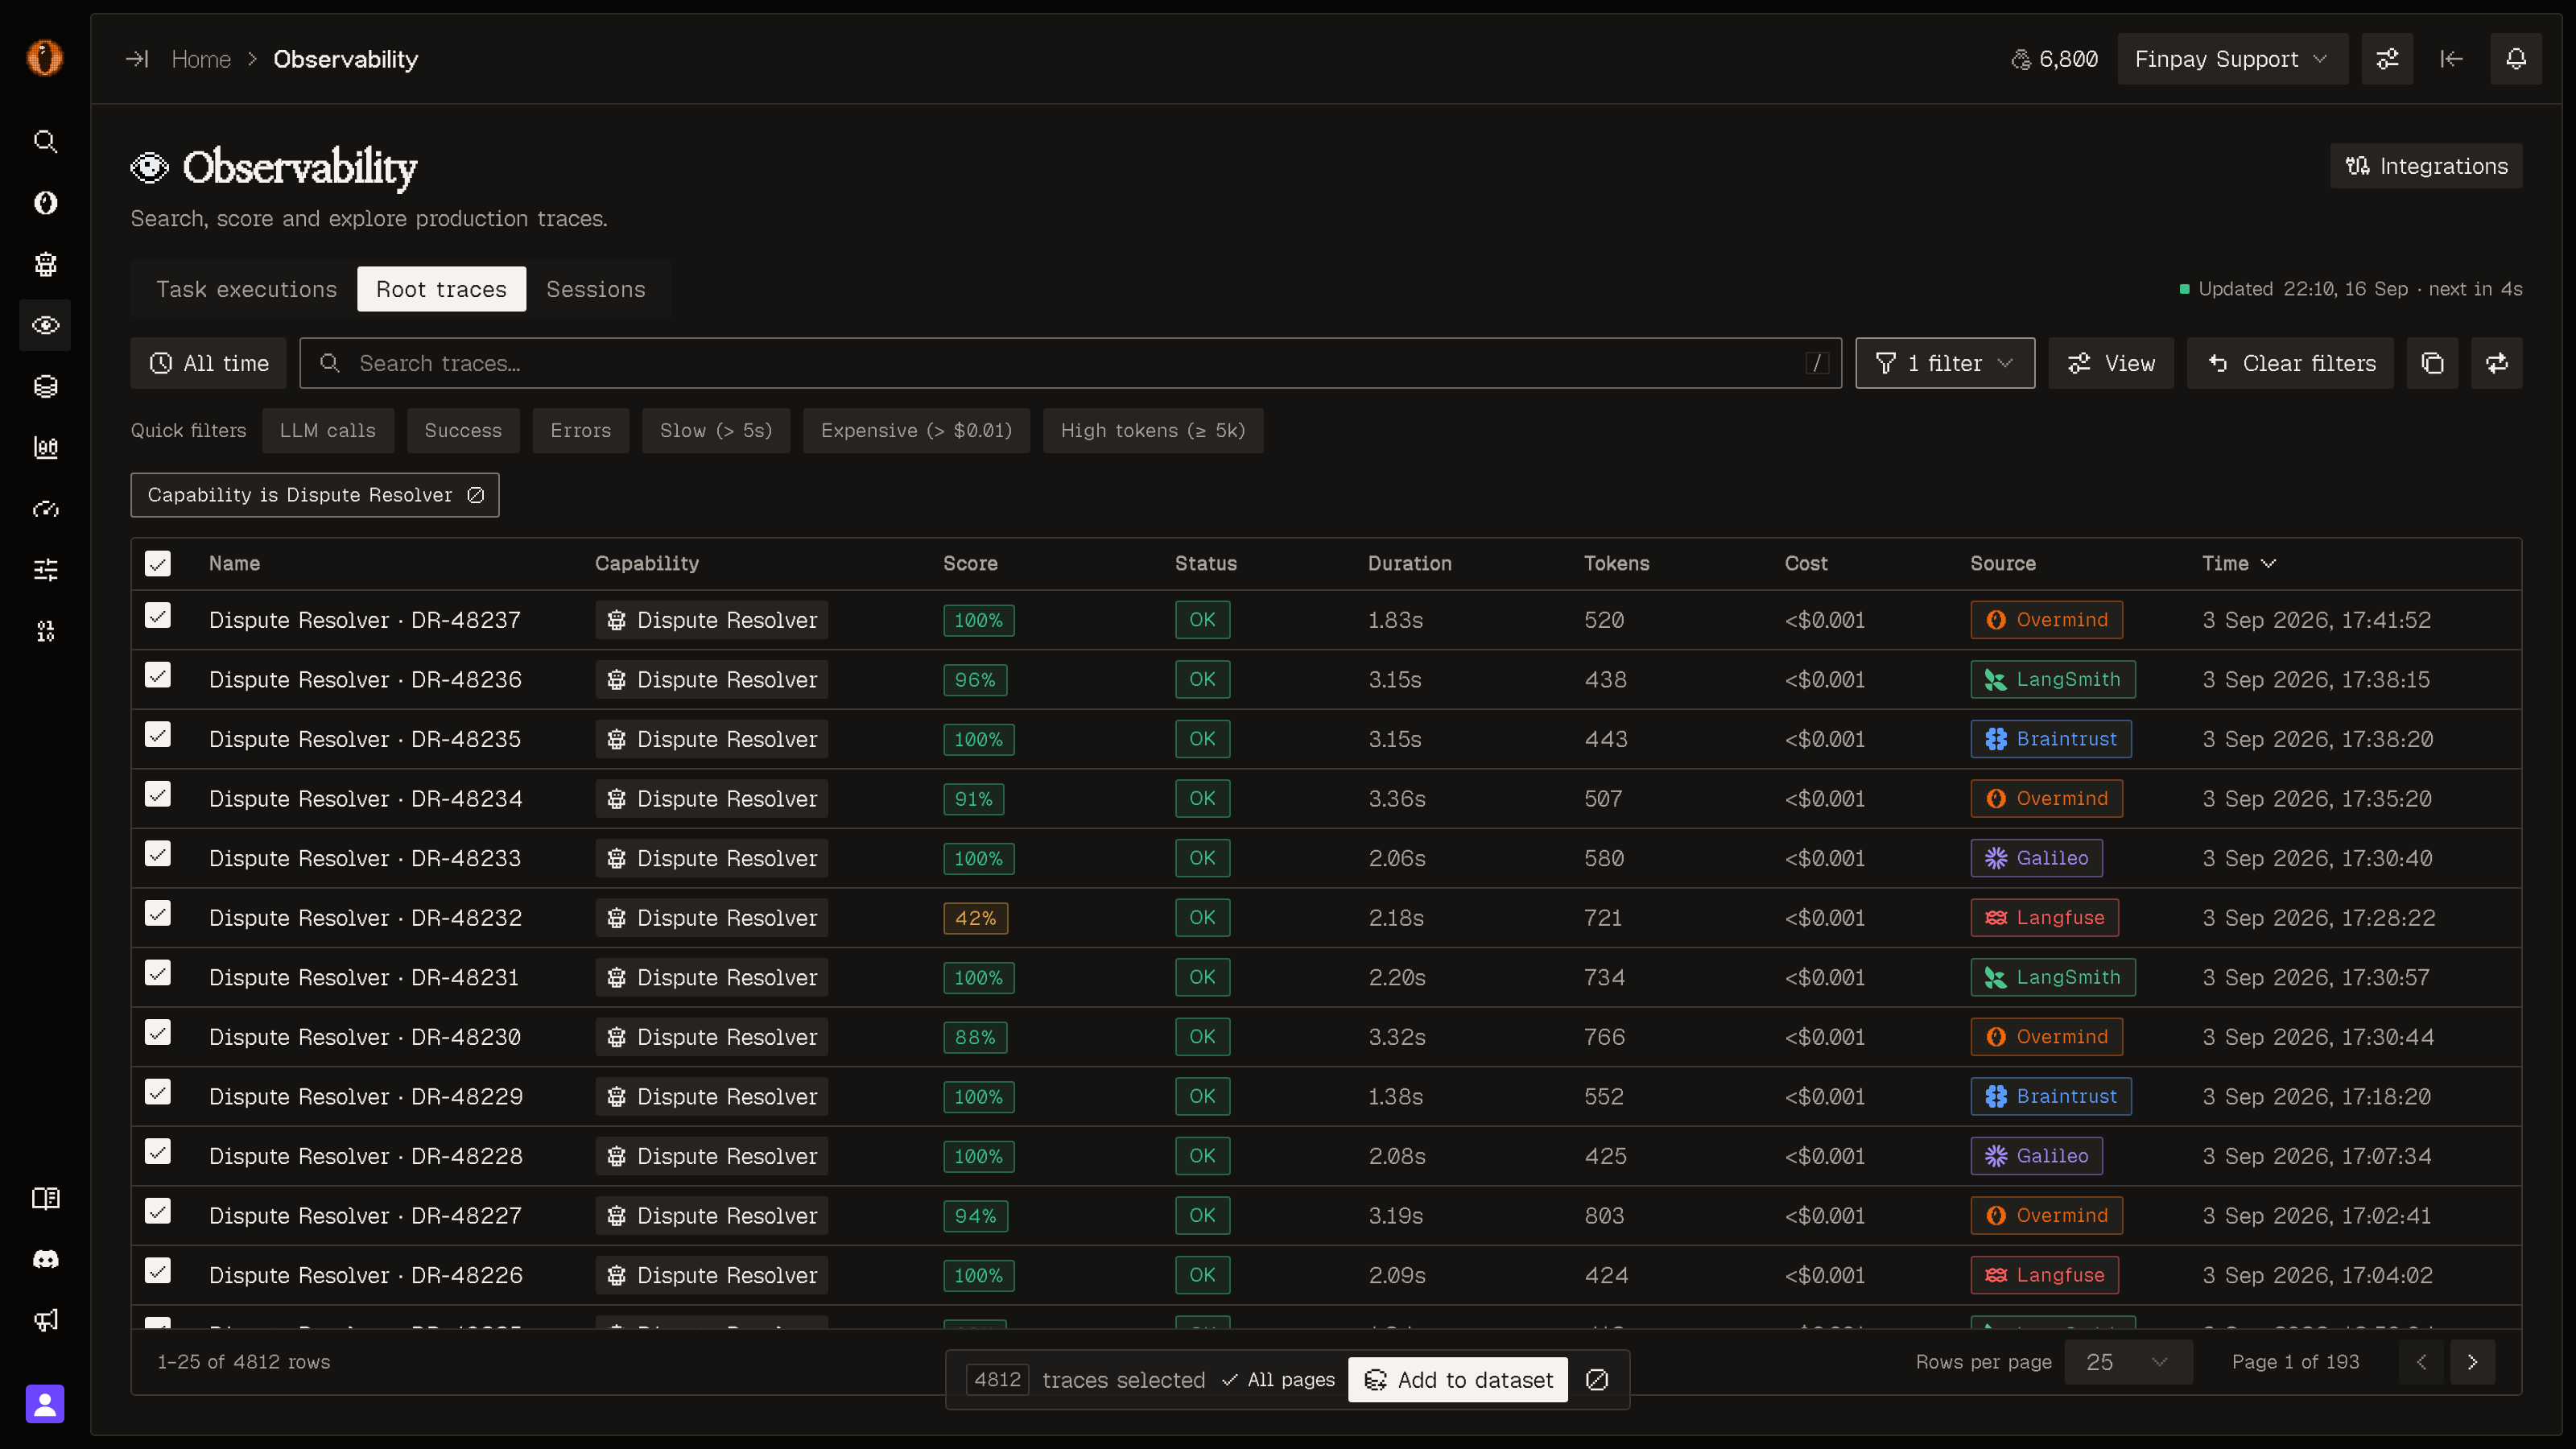
Overmind ingests production traces from your observability providers (LangFuse, Braintrust, Datadog), filters out noise and failed runs, and constructs clean fine-tuning datasets.
Dataset curation from production traces
Your agent's best production runs become training and eval data. Every example is validated and checked for fit against the agent it came from, with full provenance back to the trace it started as.

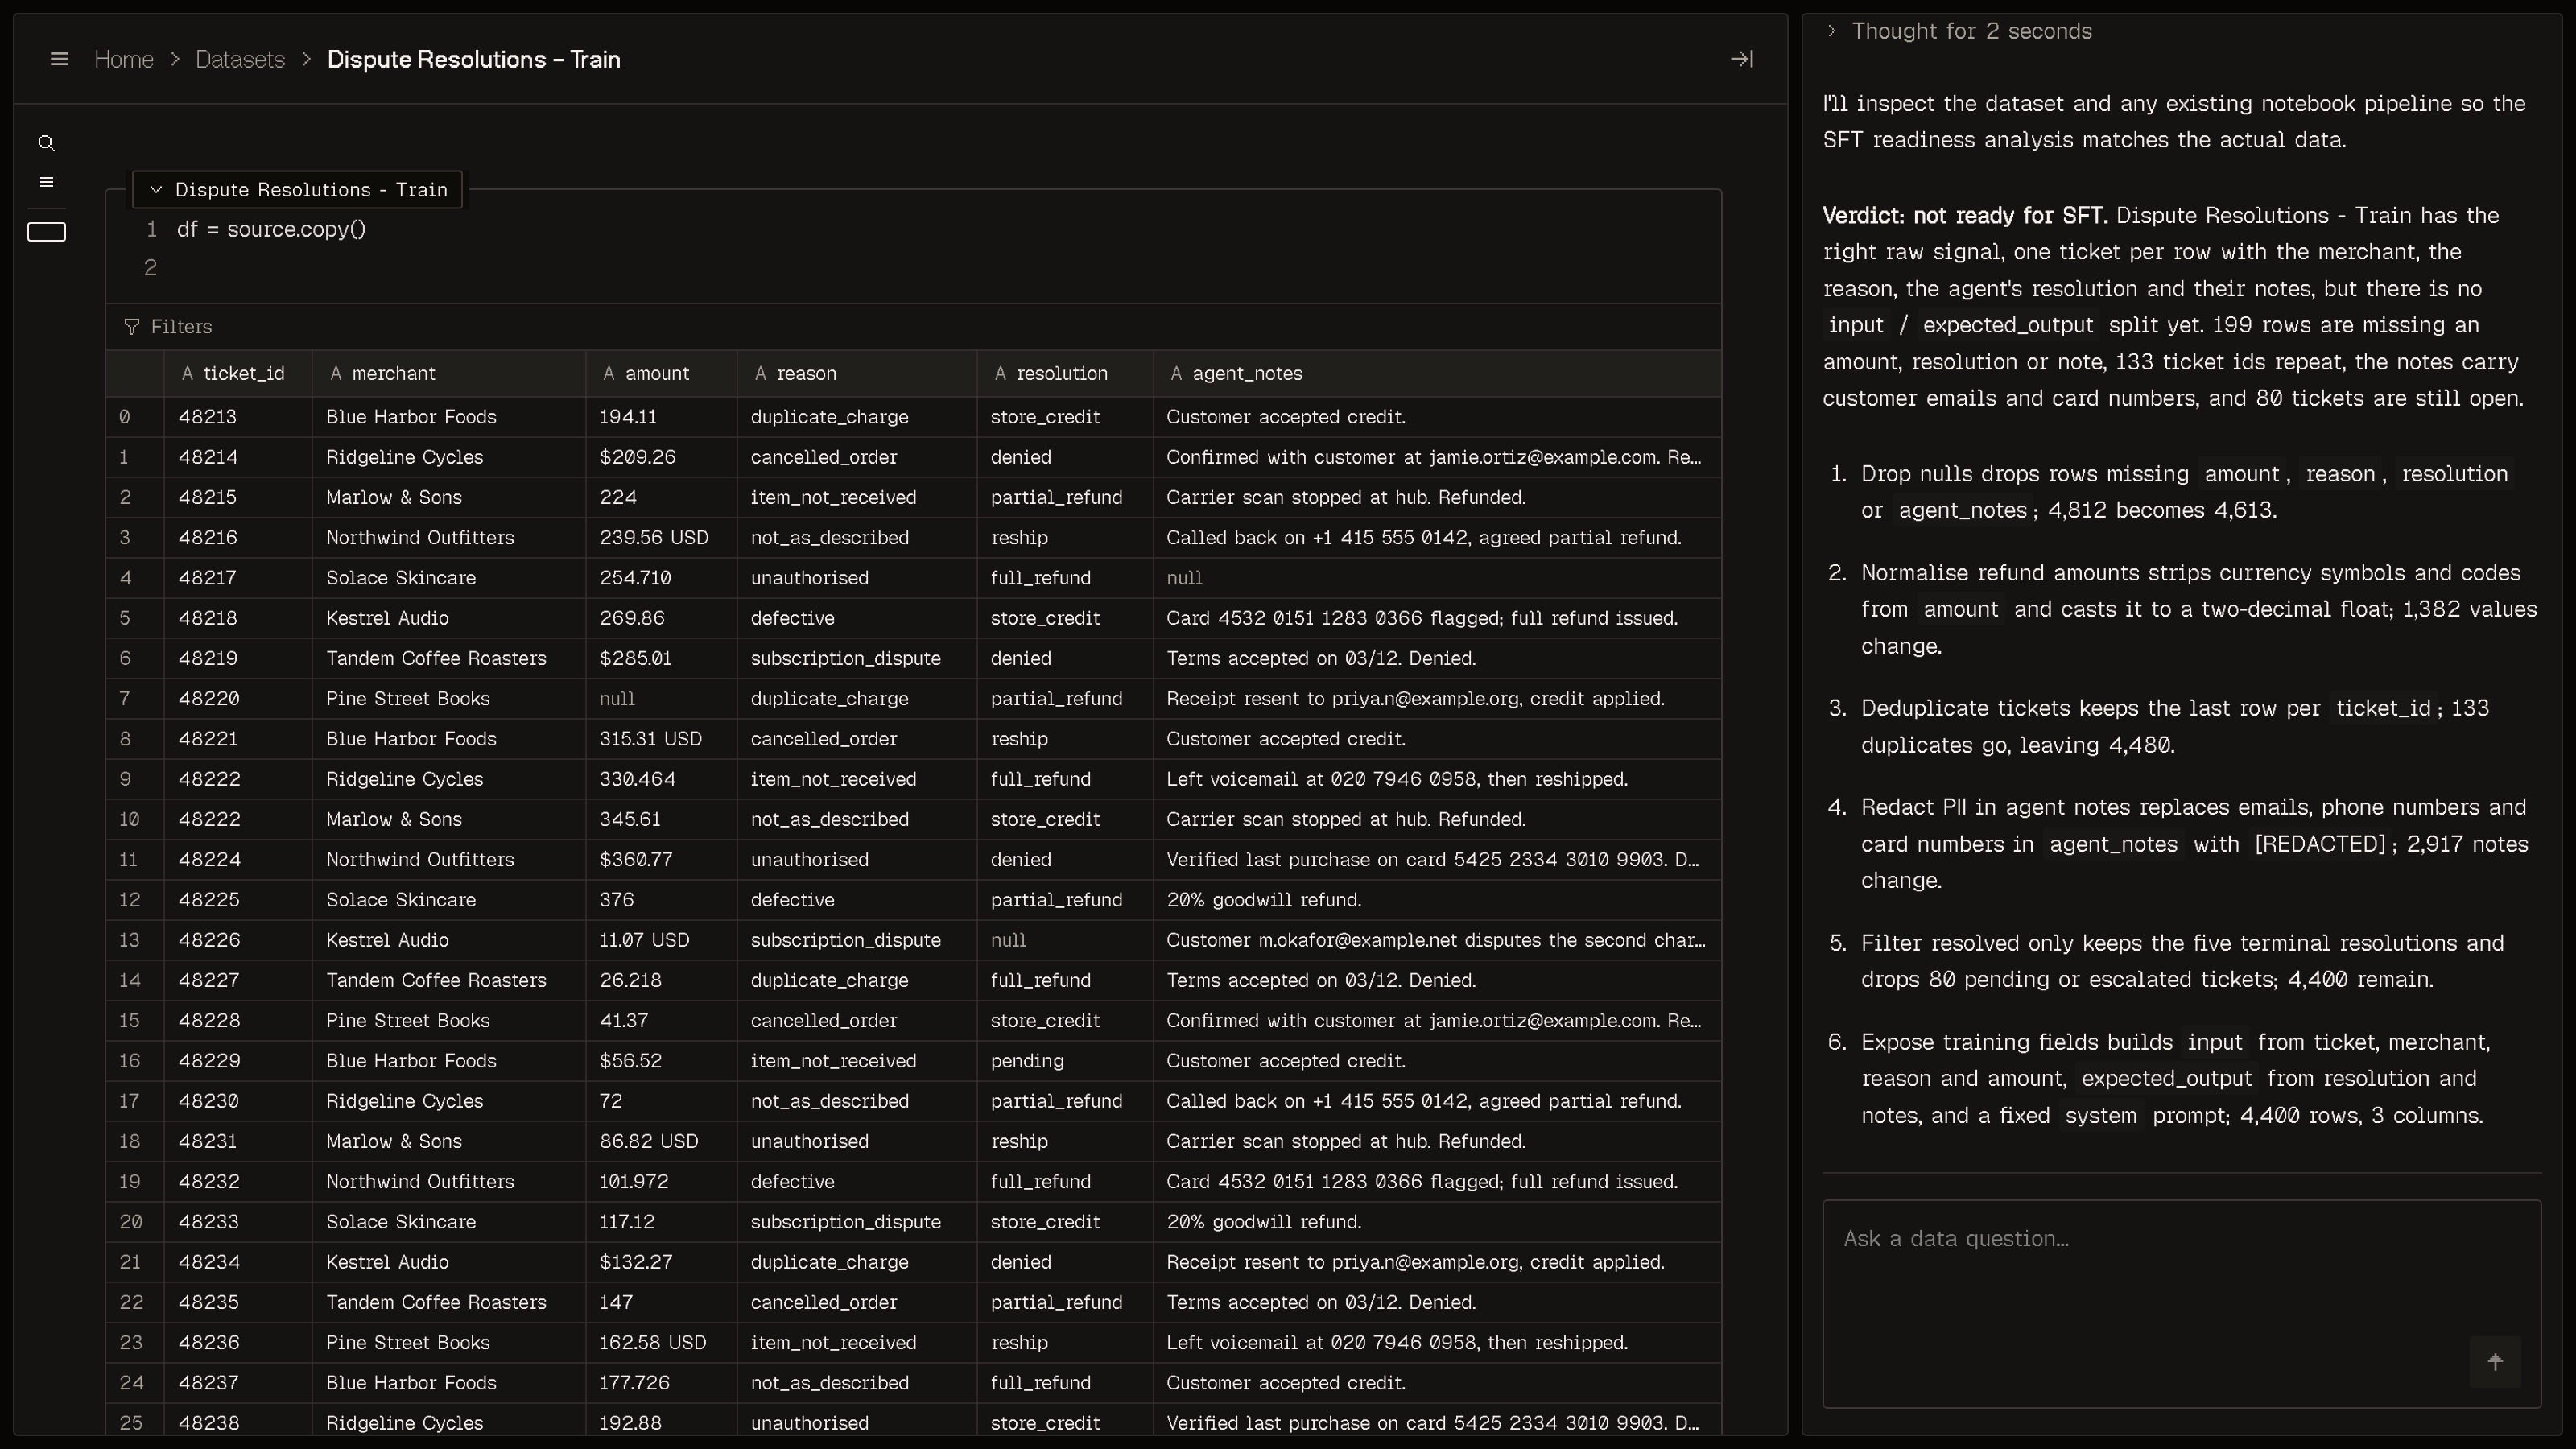
Data pre-processing in the Workshop
Clean data multiplies everything you train on it. The Workshop audits every dataset twice: deterministic checks catch duplicates, broken structure, and PII in seconds, then a coding agent reads the corpus for the problems rules miss. Every proposed fix is verified before you see it, and applying one is a click.
Adaptive Evaluation & Prompt Optimization
As code updates ship, Overmind updates your evaluations in real time. The harness automatically tests system prompts and tool-calling structures against baseline benchmarks.
Evals generated from context
Get eval coverage without writing evals. The graph knows what each agent is designed to do and how it can fail, so scoring criteria are generated for exactly that. Every run reports per-metric scores you can track across models, prompts, and releases.
Ship the winning change as a PR
The Optimiser rewrites prompts, tool definitions, and agent logic as real git diffs, each scored against your baseline on the same eval set. The winning change opens as a reviewable PR, and when tweaks stop paying off it tells you it is time to train.

One-Click LLM Training & Deployment
Train low-cost open-weights models tailored specifically to your tasks. Host with Overmind or deploy back to your preferred inference provider with full ownership of weights.
Automate model training
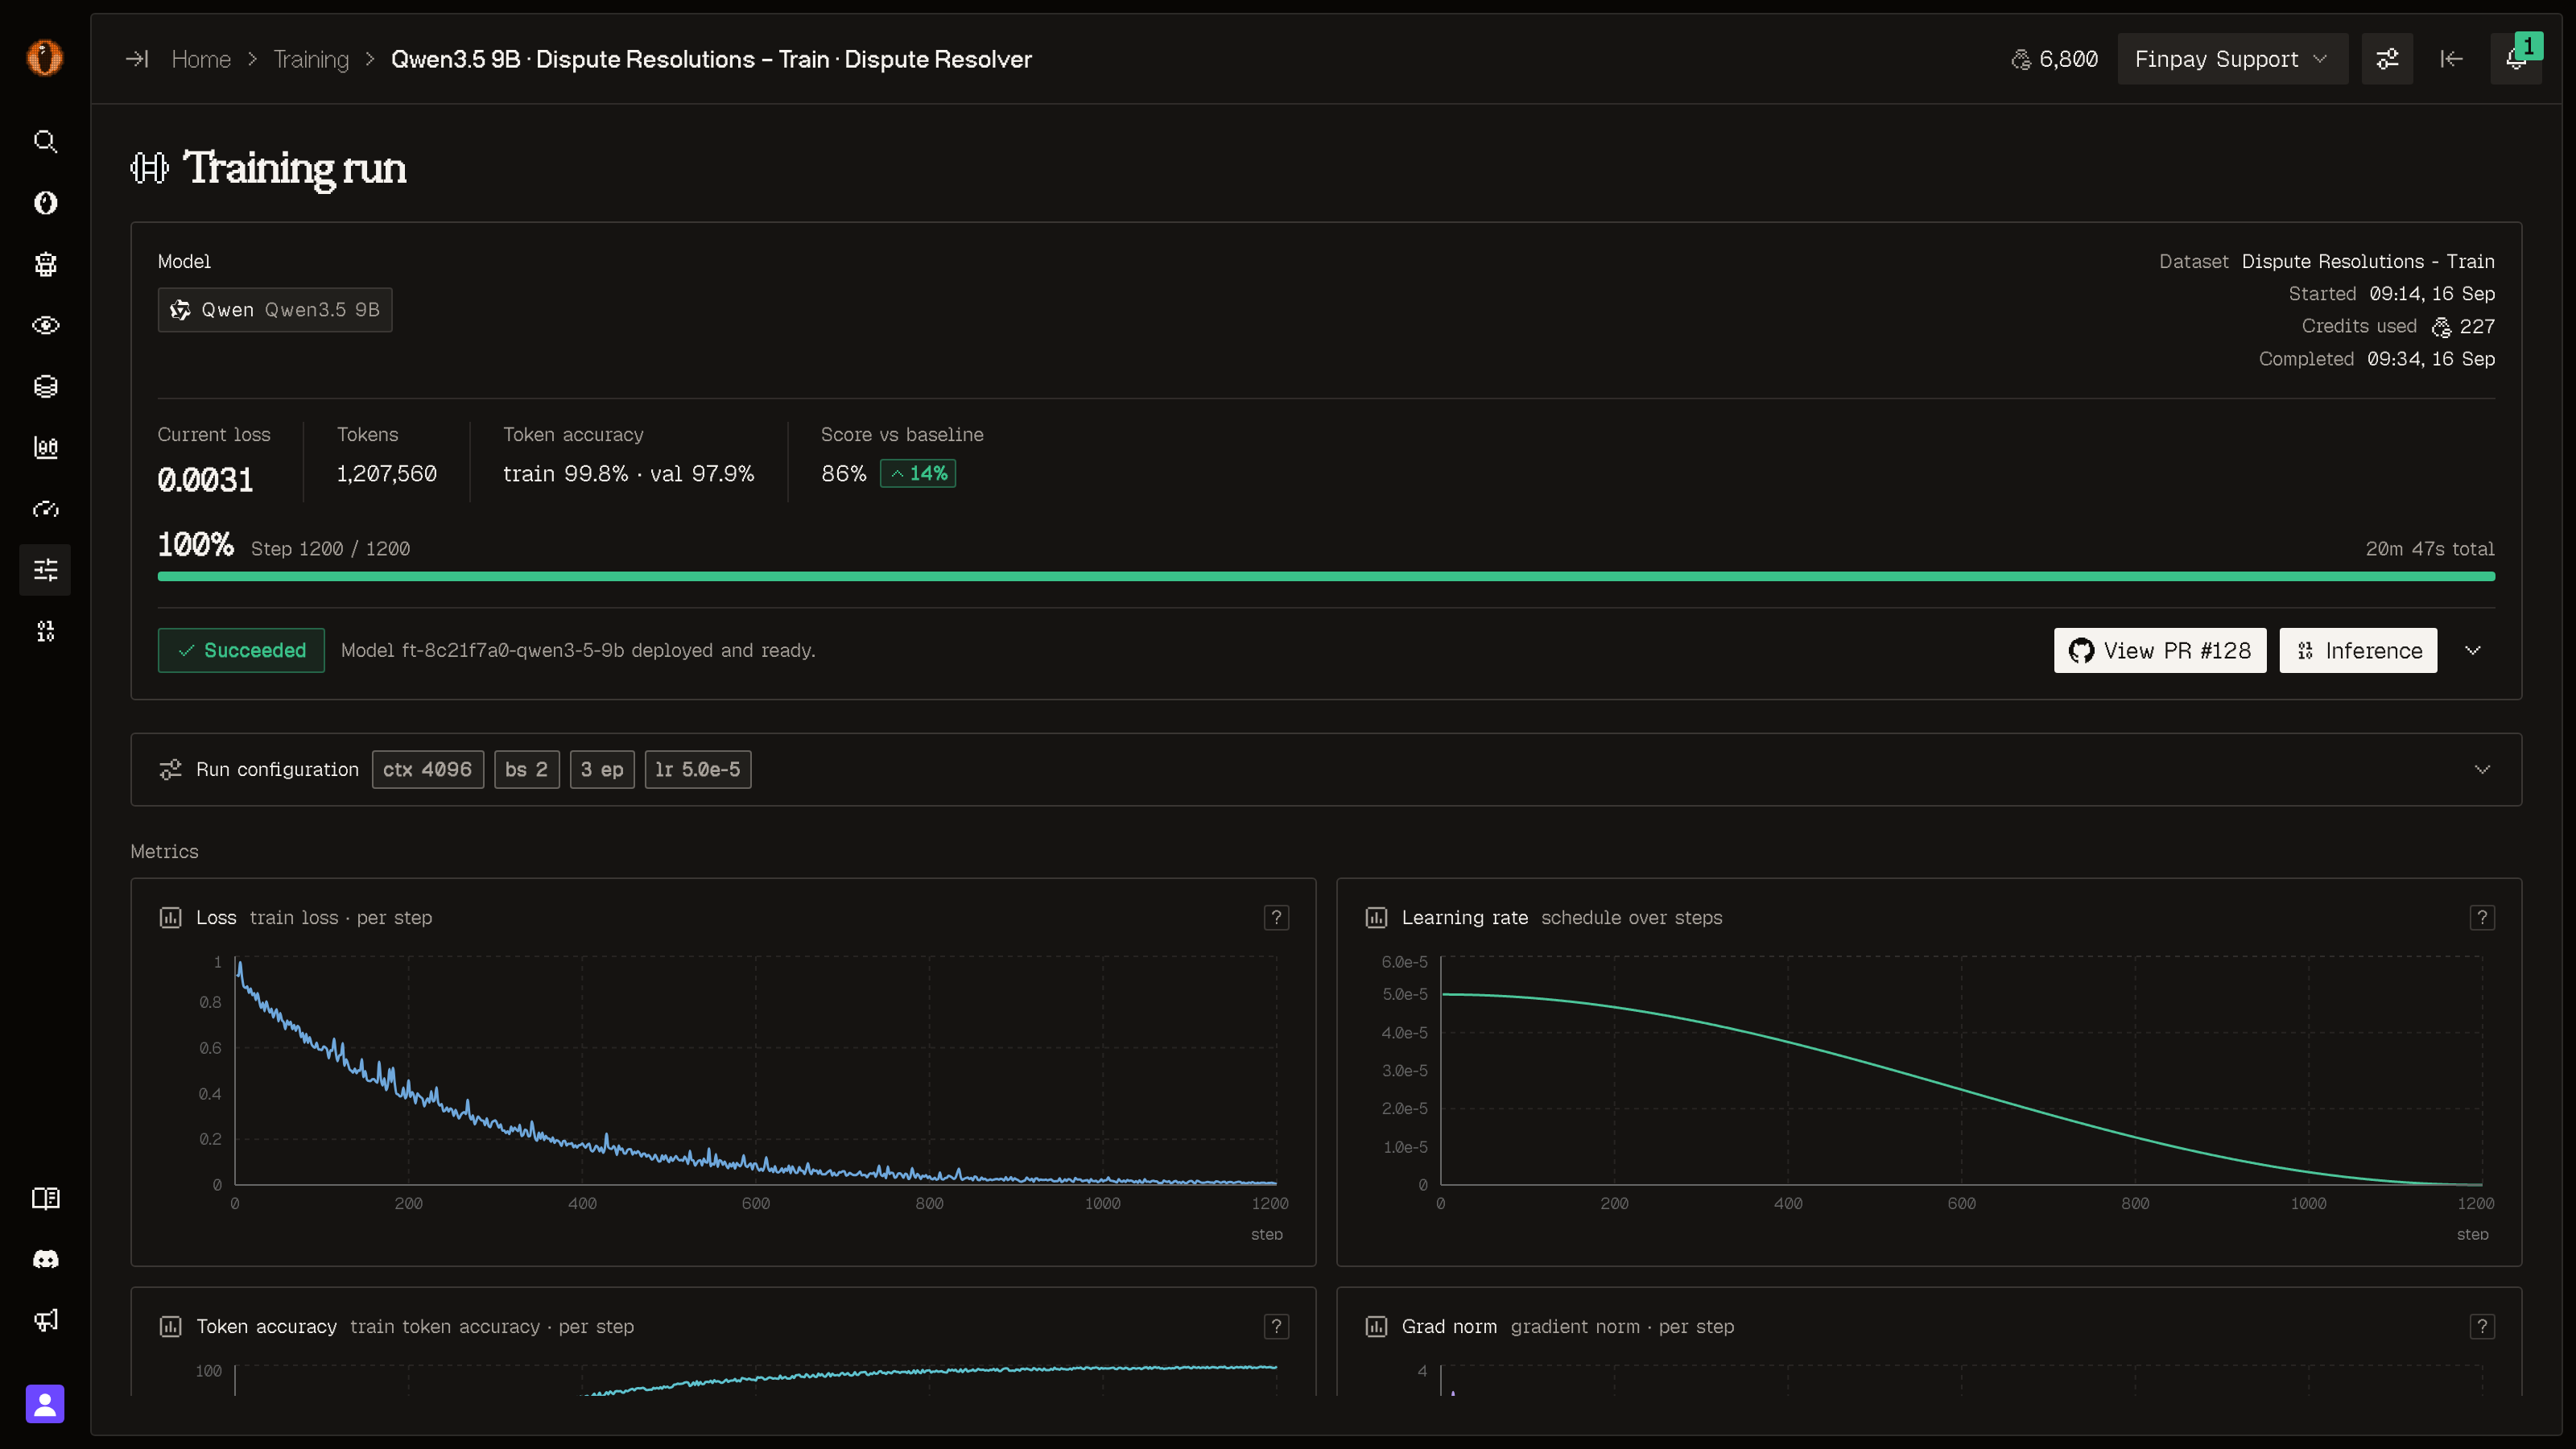
Training your own model takes a couple of clicks, because the hard decisions are already made by your data. Overmind recommends the model tier and hyperparameters, estimates cost and duration before you commit, and charts progress live. Deploy on Overmind's inference or your own stack.
Intelligence-Grade Foundations
Built by AI & Defense Intelligence Pioneers
Overmind is engineered on secure, robust foundations, not fragile wrappers. Founded by security engineers with combined decades of experience across defense intelligence, ML infrastructure, and fintech hyper-scaling.

Air-Gapped & On-Prem Deployment
Run the entire harness inside your private cloud or local environment.

Zero Third-Party Training
Your proprietary operational data never leaves your pipeline to train public foundation models.

Deterministic Validation
Advanced verification harnesses ensure model outputs are empirically tested before deployment.
Own the model your product runs on
Create a free account and get started